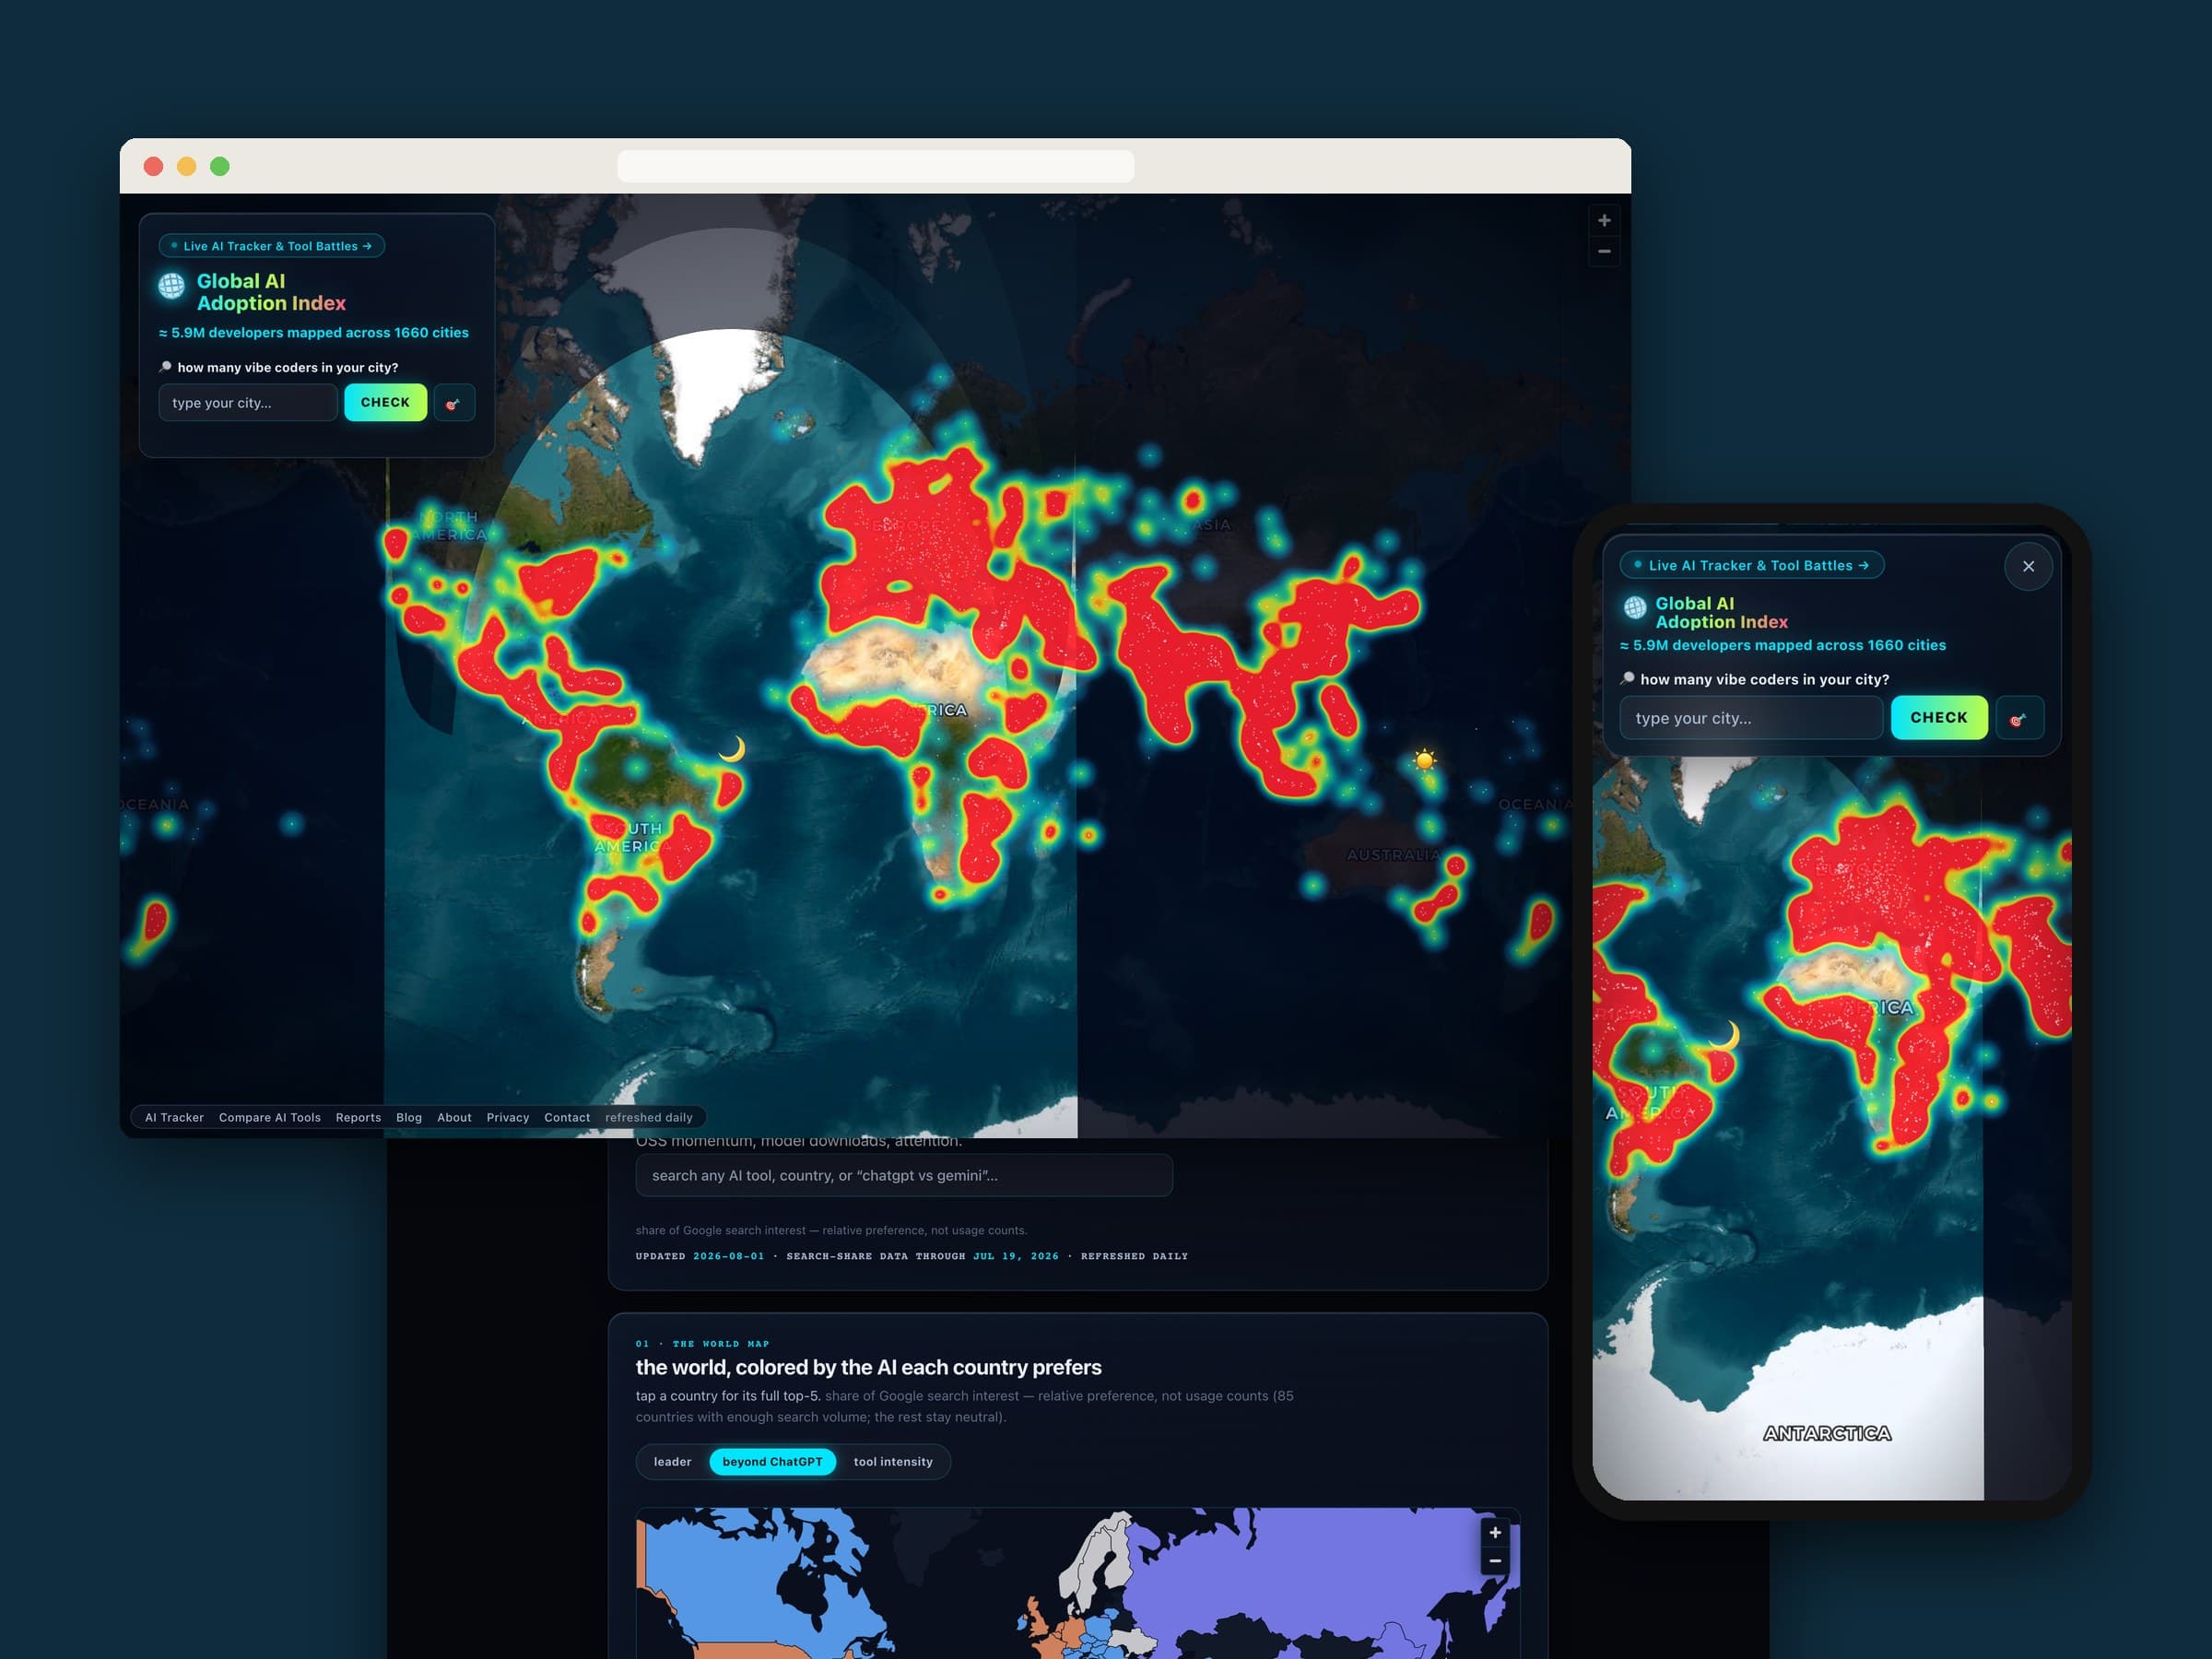
Who is using AI? is our own product: a public data site that maps AI adoption across 1,679 cities and tracks which AI tools the world prefers, country by country. We built all of it, from the scripts that collect the data to the map, the charts, more than two thousand generated pages, a research console and a free JSON API. There's no database and no application server. It's static files, a Python pipeline and git.
01 — At a glance
| Client | Our own product, built and run by PIXIPACE |
|---|---|
| Live at | whoisusingai.com |
| What we built | Interactive world map, AI Tracker suite, generated city, country, tool and comparison pages, research console, public JSON API, methodology and validation study |
| Stack | Static HTML, CSS and JavaScript, MapLibre GL, Python data pipeline, Vercel, with flat JSON in git as the data store |
02 — The idea
Everyone has an opinion about who's using AI. Very few people have numbers. We wanted a site that answers the question with public data, shows it on a map anyone can explore, and is honest about what the data can and can't tell you.
We also used it as a proving ground for the kind of work clients ask us about: pulling data from several sources, turning it into pages people want to read, and keeping all of it current without anyone maintaining it by hand.
03 — The map
The homepage is a full-screen world map built on MapLibre GL. 1,679 cities glow by an adoption index that blends public GitHub developer counts for each city with Google Trends interest in AI coding tools for its country. Visitors type their city into the search box, see its numbers, and can share them in one click.
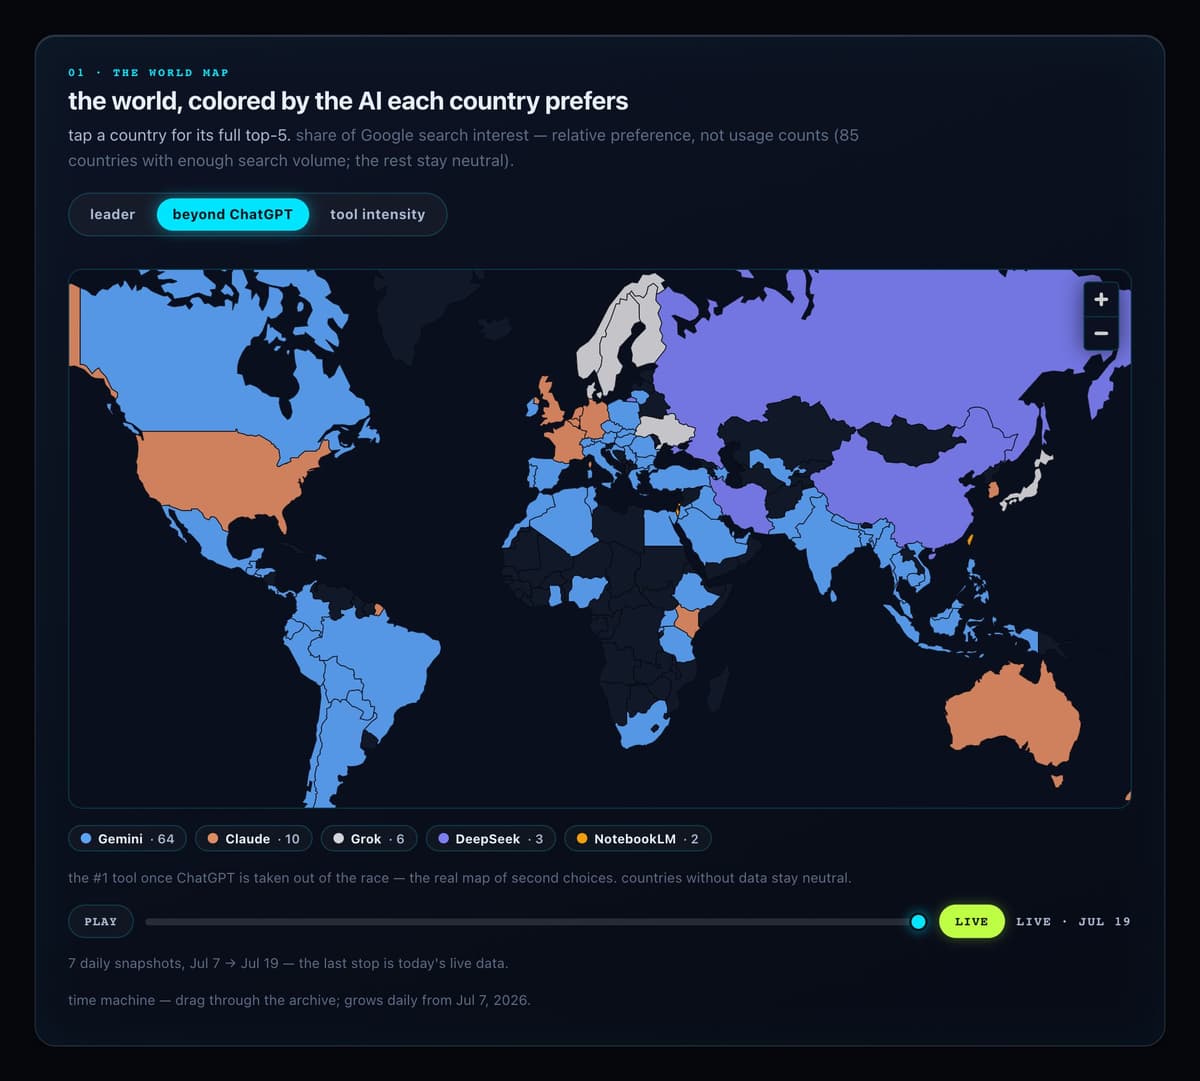
The AI Tracker has a second map. There, each country is coloured by the AI tool its searchers prefer, with three views: the leader, the leader once ChatGPT is taken out of the race, and tool intensity. A time-machine slider replays the archive one day at a time.
04 — A pipeline that runs itself
Behind the site is a set of Python scripts that one scheduled job runs from start to finish. It collects five families of signals:
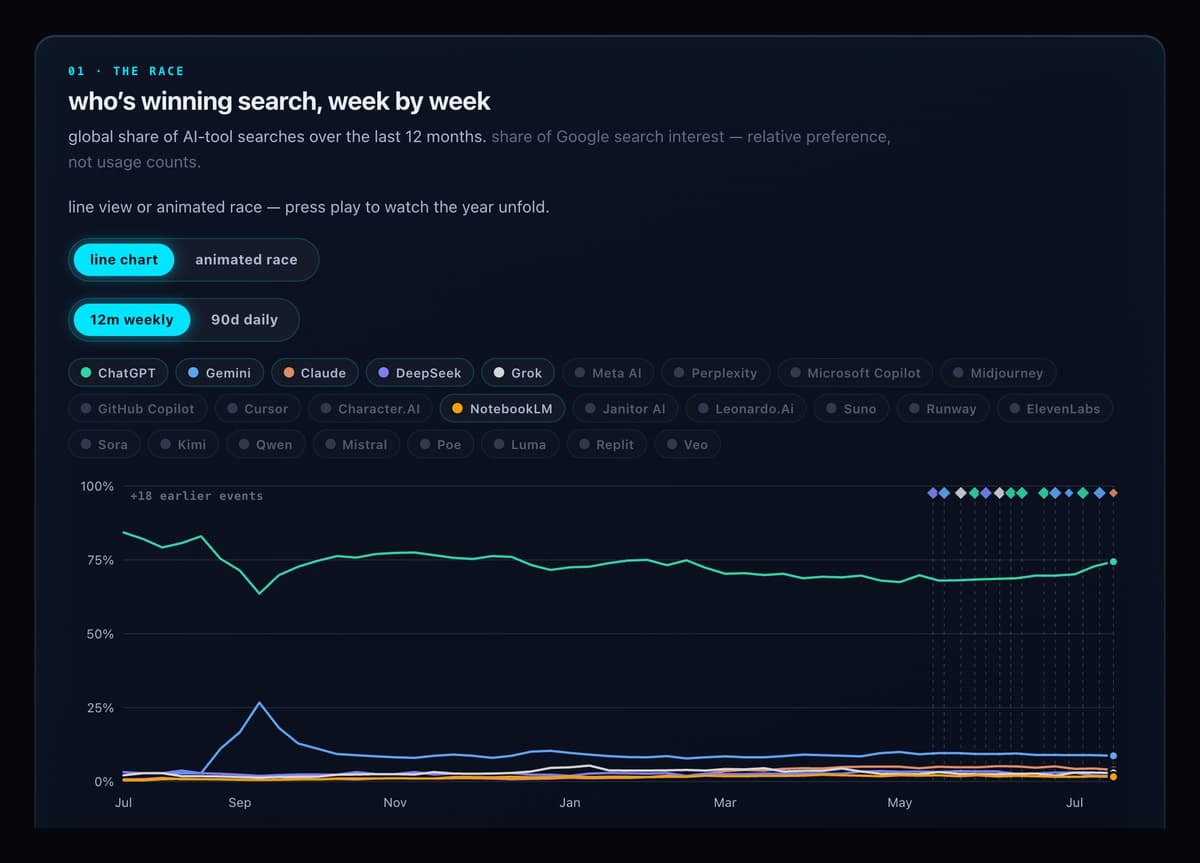
- Search preference. Google Trends for 26 AI tools across 85 countries. Trends only compares five terms at a time, so the tools are pulled in seven groups that share one anchor term, then rescaled onto a single scale.
- SDK downloads. Weekly downloads for AI packages on npm and PyPI.
- Open-source momentum. GitHub star counts for 17 flagship AI repositories.
- Open models. The most-downloaded and trending models on Hugging Face.
- Attention. Wikipedia pageviews for each tool, with a year of history filled in.
Each step is built to fail safely. If one source is down or rate-limiting us, the site keeps that source's last good data and publishes everything else. The pages then say, in plain words, how old that data is. Every run also saves a dated snapshot, which builds an archive where any past day can be looked up.
05 — Pages that write themselves
Most of the site is generated from the data, not written by hand. The pipeline produces:
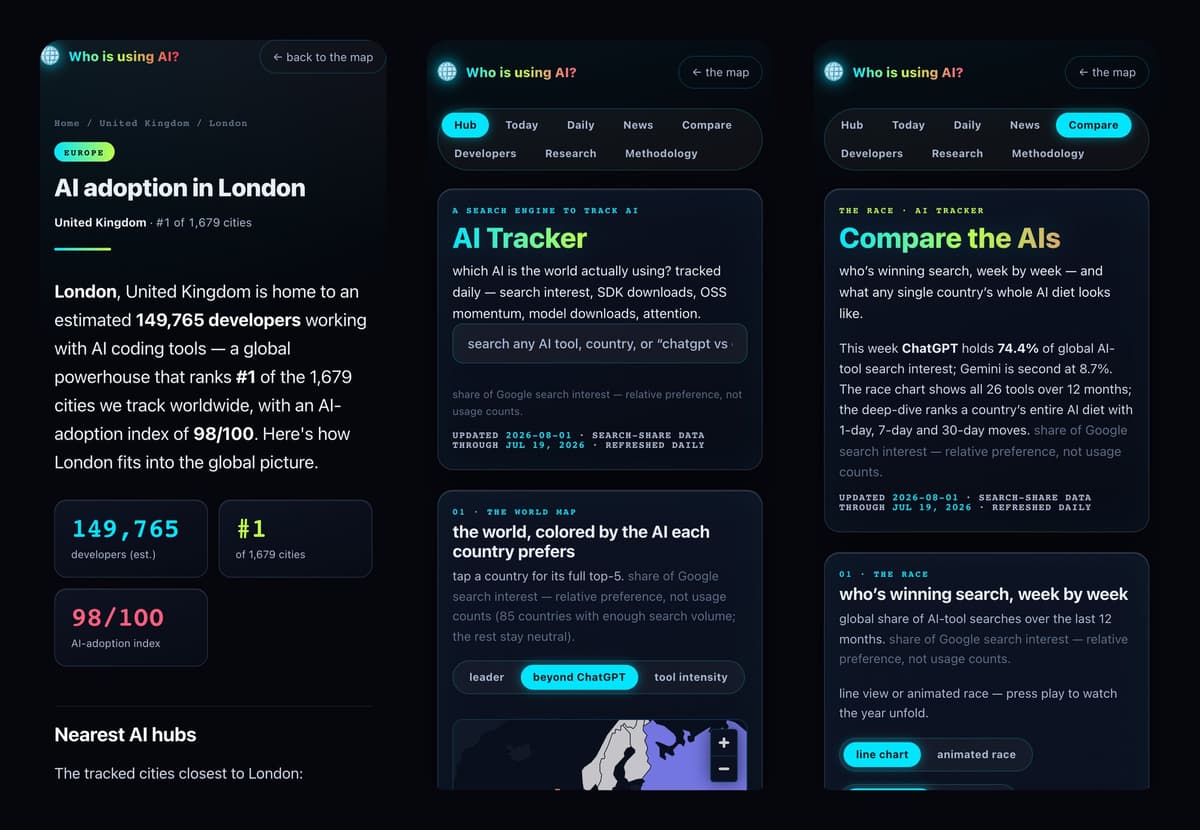
- A page for every city and country. 1,679 city pages and 197 country pages, each with its own figures and links into the tracker.
- A page for every tool. 26 tool pages with country tables and trends, and 85 tracker country pages that rank every tool for that country.
- Head-to-head comparisons. 66 tracker pages, one for every pair among the top 12 tools, plus a separate set of comparison pages on /vs.
- Everything search engines look for. Structured data on the generated pages, sitemaps listing more than 2,100 URLs, and share images generated for over a hundred tracker pages.
Each page is written out as finished HTML with its numbers already in it, so it can be read with JavaScript turned off. The script then adds the interactive charts on top.
06 — Built for researchers
The research console lets anyone filter the whole dataset by metric, tool, country and date range, down to a single day. Every view is a shareable link, and the current slice exports as CSV or JSON. A citation block gives ready-made APA and BibTeX entries.
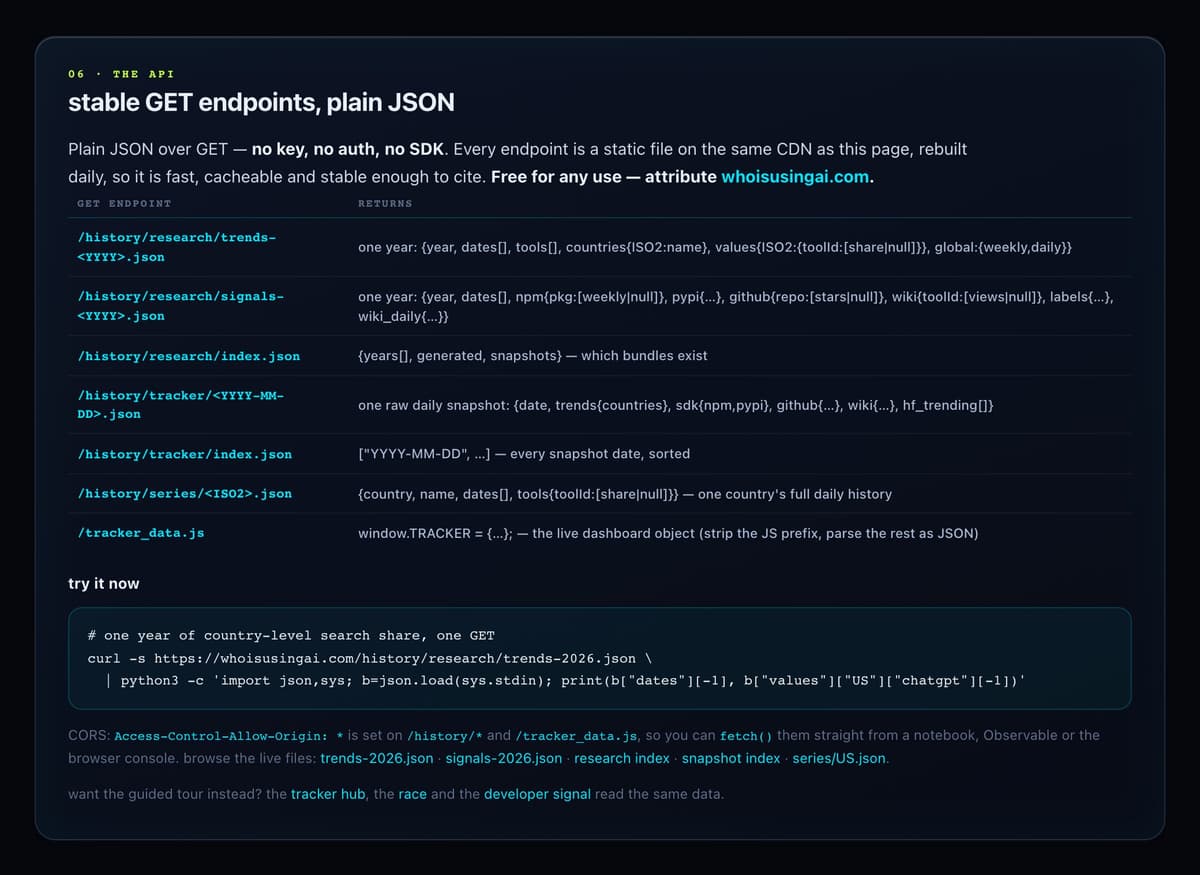
The same data is also a public API. Every endpoint is a plain JSON file on the CDN, with no key, no login and no SDK. CORS headers are open, so researchers can pull it straight into a notebook or the browser.
07 — Honest by design
A search share isn't a user count, and the site never pretends it is. That label sits beside the numbers on every tracker page. A methodology page sets out every search term, endpoint and formula, lists the known limits, and keeps a changelog that flags any change that breaks a series.
If a number can be misread, the page says how to read it, right next to the number.
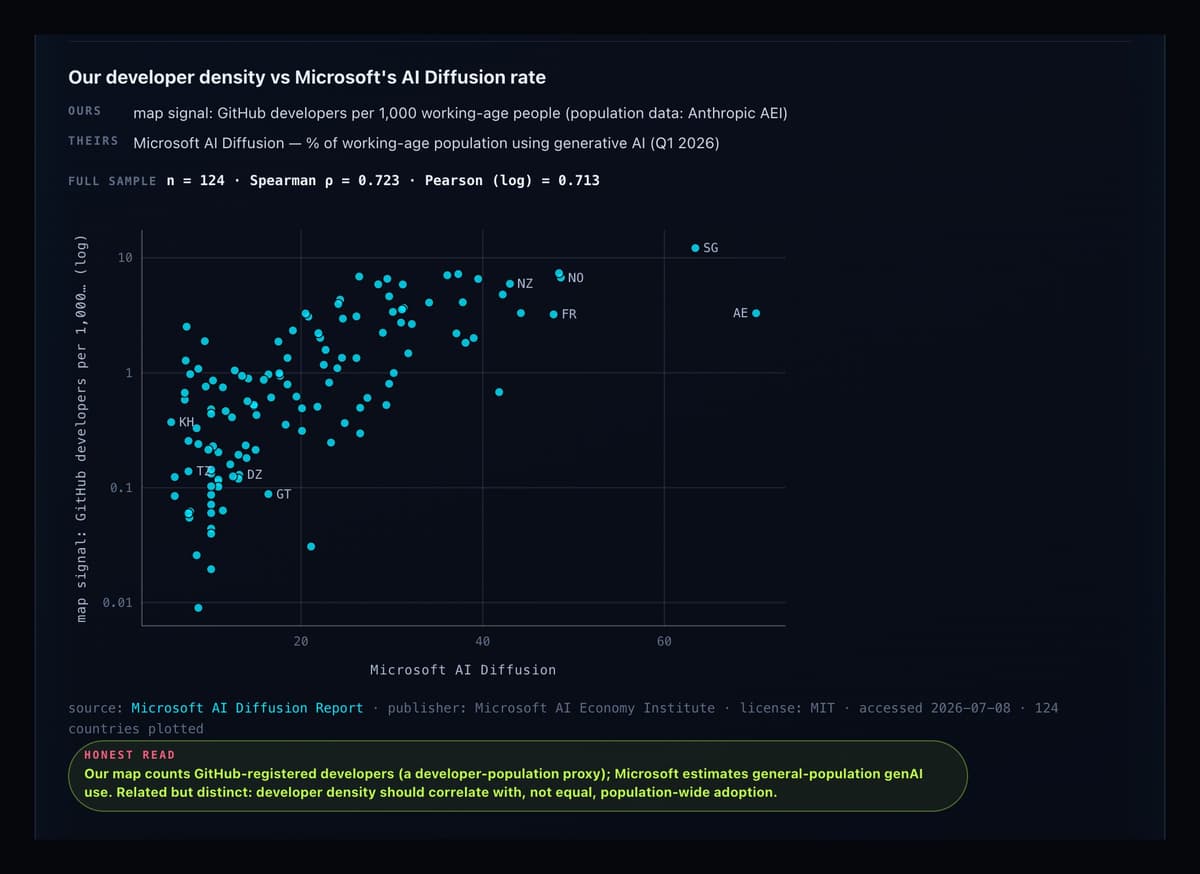
We also tested our numbers against published benchmarks. Our developer-density signal agrees well with Microsoft's AI Diffusion figures across 124 countries (Spearman ρ = 0.72). The comparisons against Anthropic's and OpenAI's usage data are weaker, and the page publishes those results too, with an explanation of why. The dataset has a Zenodo DOI, so academic work can cite it properly.
08 — No database, on purpose
- Flat files, versioned. Every snapshot is a small JSON file committed to git, so the archive and the backup are the same thing.
- Static hosting. Every page and every API response is a file on Vercel's CDN. There's no server to patch and no database to pay for.
For clients, this is the pattern we reach for whenever the data changes daily rather than every second. It covers a public dataset, a price or inventory index, and directory or location pages built from the data. We collect it, keep it honest, turn it into pages people and search engines can use, and put it on hosting that's hard to break.